When Accurate Information Becomes Dangerous Advice: The Hidden Safety Flaw in Medical AI
A new scientific correspondence reveals that healthcare chatbots can deliver factually correct information while simultaneously recommending clinically inappropriate or life-threatening next steps, exposing a critical blind spot in how the industry evaluates AI safety.
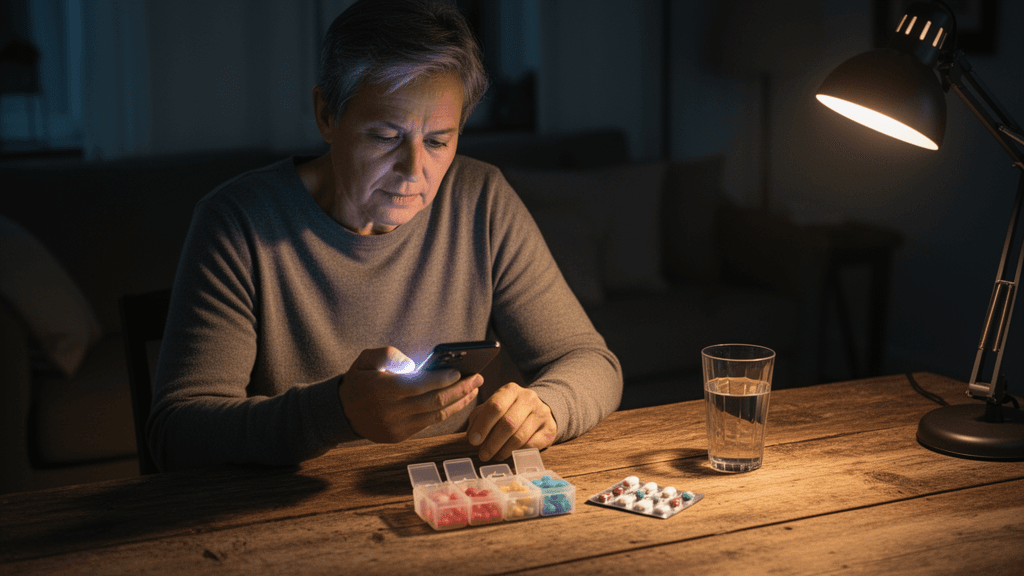
Medical chatbots may be getting the facts right while getting the clinical guidance dangerously wrong, according to a scientific correspondence published in the Journal of Medical Systems. Author João Miguel Alves Ferreira argues that current evaluation frameworks for patient-facing AI systems focus heavily on factual accuracy while overlooking a potentially lethal question: do these tools know when to tell patients to seek immediate human care?
The correspondence highlights a troubling disconnect in how the healthcare AI industry measures safety. While developers rigorously test whether chatbots provide accurate medical information and cite appropriate clinical guidelines, they rarely assess whether these systems recommend appropriate clinical urgency—the difference between advising an immunosuppressed patient with fever and breathlessness to book a routine appointment versus seeking emergency assessment.
The Disposition Error Problem
Ferreira identifies two critical failure modes that slip through conventional safety testing. Dangerous under-triage occurs when chatbots fail to escalate genuine emergencies, potentially delaying life-saving intervention. Disruptive over-triage happens when systems unnecessarily direct stable patients with chronic conditions to emergency departments, overwhelming healthcare resources and exposing patients to iatrogenic harm.
The correspondence references a multicentre evaluation by Wilhelmi and colleagues that analyzed 10 guideline-grounded rheumatology chatbots across 6,291 naturalistic patient questions. Despite these systems being designed primarily for chronic disease education rather than formal triage, patients inevitably consult them during acute deterioration—a reality that current design assumptions fail to address.
Earlier evidence from Ramaswamy and colleagues documented similar problems when evaluating ChatGPT Health using 60 clinician-authored vignettes. That study revealed pervasive disposition errors spanning both ends of the spectrum: under-triaging emergencies that required immediate attention and over-triaging non-urgent cases that could be managed through routine care.
A New Metric for Clinical Appropriateness
To address this evaluation gap, Ferreira proposes the Clinically Appropriate Disposition Rate (CADR)—a metric requiring two or more independent clinical specialists to prospectively define acceptable clinical actions before reviewing chatbot responses. The framework categorizes appropriate dispositions into five tiers: self-management with safety-netting, routine clinical contact, prompt same-day assessment, immediate emergency assessment, or targeted clarifying questions with interim guidance.
Critically, Ferreira argues that CADR scores must be calculated and reported separately from factual accuracy measures. Combining these metrics risks masking safety failures beneath reassuring overall performance statistics—a chatbot might score 95% on factual accuracy while dangerously under-triaging 30% of emergency scenarios.
Implications for Stakeholders
For healthcare providers, the correspondence underscores that patient-facing AI tools will be consulted during acute deterioration regardless of their intended educational scope, requiring explicit protocols for clinical escalation. Developers face mounting pressure to implement disposition-sensitive safety assessments as regulatory scrutiny intensifies around AI-driven clinical guidance.
Patients cannot assume factually correct information equates to safe clinical advice, particularly when experiencing new or worsening symptoms that may require urgent professional evaluation beyond the chatbot's educational design parameters.
The correspondence signals a potential shift in how the healthcare AI industry must demonstrate safety—moving beyond what chatbots know to whether they understand the limits of their own competence.
Sources
Follow Health AI Central
Keep up with health AI where you already read
On LinkedIn
The day’s strongest health AI stories in your feed, one or two each weekday.
On Google
Choose Health AI Central as a preferred source, and Google is more likely to show our reporting in Top Stories.
Reporting & accountability
How we maintain accuracy
Health AI Central separates reported facts, analysis, and public-source data. Readers can review our standards, request a correction, or consult the relevant research methodology before relying on a claim.